AISTORSApplied AI and cloud engineeringBook a 30-minute call

AISTORSServicesAI agents and assistants

Service 01

AI agents that run the work.

Inside the system, not beside it.

For operations, service and support teams whose queues are growing faster than their headcount. You have work that arrives in a queue, follows a rule somebody already wrote down, and still needs a person to read it, retype it into a second system and close it. We build agents that do that work inside the systems you already run, with a human approval step wherever being wrong carries a cost.

Book a 30-minute call
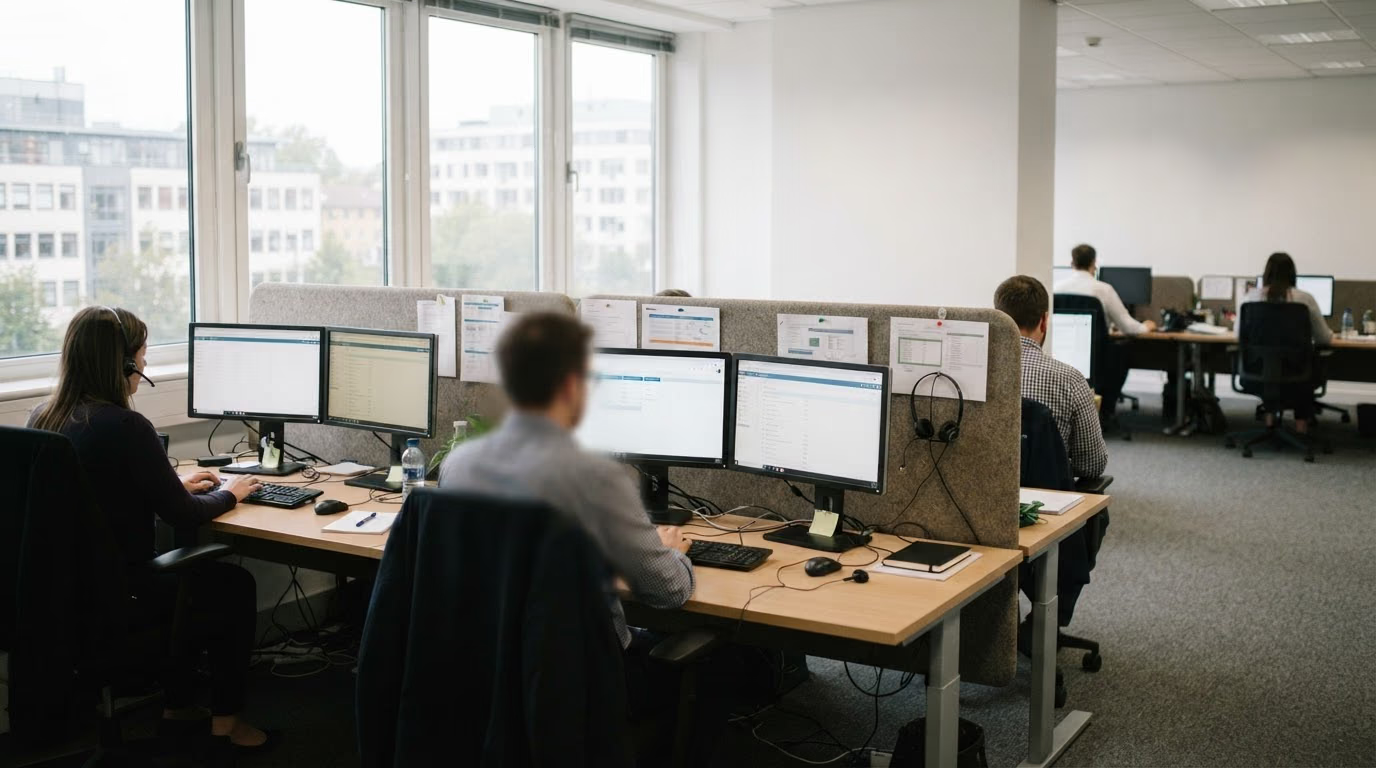
A small service operations floor in daylight, with queue and case lists on screen, headsets on the desks and printed reference sheets pinned to a low partition.
Most of this work already has a queue, an owner and a rule for what happens next. That is what makes it safe to put an agent inside it, and what makes the result measurable.
01

Who this is for

If the left column is not you, tell us on the call and we will say what would actually help instead.

This is for you if

  • Work arrives in a queue and follows a known rule. Enquiries, tickets, cases or orders that somebody reads, judges against a policy, then retypes somewhere else.
  • The volume is high enough to matter. Hundreds a week rather than a handful, so the build repays itself and accuracy can be measured rather than felt.
  • You have a system of record. A CRM, service desk, ERP or practice system that holds the truth and can be read and written through an interface.
  • Somebody on your side can say what correct looks like. A person who can review a sample of real cases and tell us plainly when the agent got it wrong.
  • The audit trail matters. Regulated or reviewed work where who decided what, and when, has to be recoverable a year later.

This is not for you yet if

  • The process changes every week. Automating an unstable procedure locks in this week's version. Stabilise it and this becomes straightforward work.
  • Nobody has ever counted it. We will time it with you in the Diagnostic, but until then there is no honest way to price the build or prove the result.
  • The record cannot be reached. If it only exists in somebody's inbox, or in a system with no interface we can drive, that is a data problem before it is an agent problem.
  • You want a website chatbot. Cheaper tools do that well and we would be the wrong spend. We will tell you which ones.
  • The volume is genuinely low. Below a certain frequency the build costs more than the work it saves, and we would rather say so than sell it.
02

What we fix, and how

Four things go wrong with agent projects. Each one has a specific answer, agreed before any code is written.

PROBLEM 01

Your team is the integration layer

What we do. People are the copy and paste between two systems nobody ever connected. We put the agent inside those systems, reading and writing through their own interfaces under your credentials, so the retyping stops instead of moving to a new screen.

PROBLEM 02

The pilot worked and then nothing happened

What we do. Demonstrations pass because a person chose the examples. We score the agent against a fixed set of your own real cases, labelled by your team, before it ships and again on every change after that.

PROBLEM 03

Nobody will sign off something that acts alone

What we do. So it does not act alone. The boundary of what the agent may decide by itself is agreed in writing before the build and becomes a contract term. Consequential actions pass an approval gate, and the rollback path is tested rather than assumed.

PROBLEM 04

You cannot prove afterwards that it worked

What we do. We record cycle time, error rate, volume and hours before anything is built, in your systems, with the counting method written down. The same four measures are reported afterwards, so the renewal conversation has numbers in it.

03

What you get

Six agent types, all of which act inside your systems rather than describing what you should do.

What we build

  • Intake and qualification. Enquiries read, classified, enriched from your own records and routed, with the ambiguous ones escalated rather than guessed at.
  • Ticket and case triage. Priority, category and owner assigned from the content and from history, written back into the service management tool.
  • Internal question answering over your own records. Grounded in your documents with citations back to the source, so an answer can be checked rather than trusted.
  • Scheduling and dispatch. Against real availability, real constraints and real travel time, not against an idealised calendar.
  • Escalation routing. Confidence thresholds and policy rules that hand a case to a named person, with the reason recorded.
  • Drafting with a human approval step. Replies, notes, quotes and summaries prepared for a person to approve, where the consequence of being wrong is external.
  • Multi-agent workflows with handoffs. Only where a single agent genuinely cannot do the job, because every handoff is a new failure mode.
  • Voice, WhatsApp, email and Teams surfaces. Where the work already happens, rather than a new interface for someone to learn.
  • Approval gates, audit logging and a tested rollback path. On every consequential action, as a condition of go-live rather than a later phase.

What this is not

  • Not a chatbot bolted onto a website. If the agent cannot read and write in the system of record, it has not automated the work.
  • Not an agent platform of ours. Built in your tenancy, on your accounts, with your model provider contracts. Nothing of ours sits in the middle.
  • Not autonomous by default. The boundary of what it may decide alone is a contract term agreed in the Diagnostic, not a configuration flag we can widen later.
  • Not scoped without a baseline. We will not quote an agent build on a process nobody has timed, because there would be no way to tell afterwards whether it worked.
  • Not recommended everywhere. Where the process is unstable, the data unreachable, or the volume too low to repay the build, we will say so and you keep the analysis.
04

How it runs

Gartner names three causes of cancellation. Each one is addressed before the build, not after.

01

Baseline the process first

Cycle time, error rate, volume and hours on the target process, recorded in your systems before anything is built. This is what makes "unclear business value", the second cause Gartner names, impossible by construction.

3 to 5 days · Credited against the build

02

Integration and data readiness, before model choice

Which systems hold the record, which have usable interfaces, where the records disagree. Gartner predicts 60 percent of AI projects will be abandoned through 2026 for want of AI-ready data, so this is settled before a model is selected.

Findings named, not summarised

03

Evaluation set built from real cases

A fixed, versioned set of your own cases, labelled by your team, with a target accuracy agreed before the build. Without this there is no way to tell a model change from a regression, which is Gartner's third cause: inadequate risk controls.

Owned by you from day one

04

Build in your tenancy, narrow scope first

One process, in your accounts, with approval gates on consequential actions and cost instrumented per run. Gartner expects 80 percent of tangible agentic return by 2028 to come from specialised agents, so the first build is deliberately narrow.

Fixed scope agreed in writing

05

Measure against the baseline, then decide on the next one

The same four measures the Diagnostic recorded. If the numbers do not move, that is reported plainly and the second build is not automatically approved. Escalating cost is Gartner's first named cause of cancellation, and cost per completed task is tracked from the first week.

Reported against baseline · Then run

05

Platform native

Built on your platform and your model contracts. Self-hosted where the data cannot leave your estate.

Azure

Azure AI Foundry, Azure OpenAI, AI Search for retrieval, Functions and Logic Apps for orchestration, Entra ID for agent identity, content safety filters.

AWS

Bedrock with Agents and Knowledge Bases, Bedrock Guardrails, Step Functions and Lambda, OpenSearch for retrieval, IAM roles scoped per action.

Google Cloud

Vertex AI with Agent Builder, Gemini models, Vertex AI Search, Workflows and Cloud Run, BigQuery for grounding on your own data.

DigitalOcean

GenAI Platform and managed inference, DOKS for orchestration, managed Postgres with pgvector for retrieval, or open-weight models self-hosted on your own droplets.

Model providers we work with include OpenAI, Anthropic, Google Gemini, AWS Bedrock and Azure AI Foundry, on enterprise or business terms with training on your data disabled. Where residency or sensitivity requires it, open-weight models run fully self-hosted in your own tenancy. The full disclosure is on the AI capability page.

06

The evidence, if you want it

You do not need these numbers to recognise the problem. They are here because somebody in your approval chain will ask.

17%

of organisations have deployed AI agents, while more than 60 percent expect to within two years. Gartner describes this as the steepest adoption curve among the emerging technologies it measured.

Source: Gartner 2026 CIO and Technology Executive Survey, via Gartner's Hype Cycle for Agentic AI, 2026.

40%

or more of agentic AI projects are predicted to be cancelled by the end of 2027, citing escalating costs, unclear business value and inadequate risk controls.

Source: Gartner, 25 June 2025.

2 in 3

enterprises expect service providers to build and operationalise their priority use cases. One third are already scaling agentic deployments.

Source: BCG, The $200 Billion AI Opportunity in Tech Services, 2026.

Read those three together and the brief is obvious. Almost everyone intends to do this, most have not started, a large share of what does start gets cancelled for reasons that are all controllable, and enterprises have already decided not to do it alone. Gartner also expects 80 percent of tangible agentic AI return by 2028 to come from specialised, domain-specific agents rather than general-purpose ones, which is an argument for narrow scope and sector depth over platform breadth.

07

The gap between intent and working systems

Intent is near-universal. Deployment is rare. Cancellation is common. All three are published numbers.

Artifact / Agent adoption, intent and cancellation Share of organisations or projects
17 percent of organisations have deployed AI agents. More than 60 percent expect to deploy within two years. More than 40 percent of agentic AI projects are predicted to be cancelled by the end of 2027. 0 10% 30% 50% 70% SHARE 17% 60%+ 40%+ HAVE DEPLOYEDAI AGENTS TODAY EXPECT TO DEPLOYWITHIN TWO YEARS OF AGENTIC PROJECTSCANCELLED BY END 2027 THE THIRD BAR IS A PREDICTION ABOUT PROJECTS, NOT A MEASUREMENT OF ORGANISATIONS. IT IS NOT A SUBSET OF THE OTHER TWO.
Sources: Gartner 2026 CIO and Technology Executive Survey via Gartner's Hype Cycle for Agentic AI, 2026, for deployment and intent. Gartner, 25 June 2025, for the cancellation prediction. The three bars measure different populations and are shown together to make one point: the failure rate is high enough that the sequence you follow matters more than the model you pick. Gartner names the causes as escalating costs, unclear business value and inadequate risk controls. All three are addressed before a build starts rather than after.
08

Questions we are actually asked

How do we know it will not make things worse?

You do not, at the start, and neither do we. That is why the boundary of what the agent may do alone is agreed before the build and written into the contract, why every consequential action passes an approval gate, why the rollback path is tested rather than assumed, and why accuracy is scored against a fixed set of your own cases. The question is not whether an AI system will be wrong. It is what happens in the minute after it is.

Why do you insist on measuring the process first?

Because Gartner's stated causes of agentic project cancellation are escalating costs, unclear business value and inadequate risk controls, and a baseline addresses two of the three directly. Without one, there is no way to defend the spend at renewal and no way to decide what to scale. The second project then gets approved on the same evidence as the first, which is none.

Can you use our existing model provider contract?

Yes, and it is usually preferable. We build on your contracts, in your tenancy, on your accounts. If you have no provider relationship yet we will help you choose one on the merits of your workload and residency requirements, and we hold no reseller agreement or commission on any of them.

Our data cannot leave our environment. Is this still possible?

Yes. Open-weight models run fully self-hosted in your own tenancy, which is slower to build and usually costlier to run than an API, and we will tell you the trade-off in numbers rather than in principle. Region is treated as a requirement rather than a preference, and every third party in the path is listed before work starts with a standing right for you to refuse any of them.

What happens when the model underneath is deprecated?

It is planned for, because it is certain. OpenAI announced retirements from ChatGPT effective 13 February 2026 and Anthropic's published policy is at least 60 days notice on publicly released models. The version is pinned, deprecation notices are tracked, and a successor is scored against your evaluation set before cutover. That handling sits in managed operation.

Will you tell us if we should not build this?

Yes, and it happens. Where the process is unstable, the data unreachable, or the volume too low to repay the build, a no-go with the reasoning attached is the outcome of the Diagnostic. You keep the report, the baseline method and the plan. We would rather lose the build than sell one that fails.
09

Next step

Bring one process, not a strategy.

Thirty minutes, no obligation. Describe one process that is done by hand today. We will tell you whether it is a measurement problem, an integration problem or neither, and whether an agent is the right answer at all.

Starts with
The AI Readiness and Baseline Diagnostic. Three to five days, one day for small business and solo operators.
Investment
Scoped on the introductory call, and credited in full against the build that follows.
If the answer is no
You keep the report, the baseline method and the plan. No further commitment.